






Research
Why We Serve an Uncensored DeepSeek
Defenders get refused. Attackers don't.

Kimi K3 is #1 on Design Arena: Fable-tier, served at 100 tok/s. GLM-5.3 is Opus-tier with 1M context. Both on kernels tuned for agents, plus the open-weight lineup: Qwen, MiniMax, DeepSeek.
Specialized models: WarpGrep for search. Fast Apply for applying edits at 10,500 tok/s. Compact at 33k tok/sec.
DeepSeek V4.1 Flash with its refusal directions ablated. Same API and 1M context. Approved teams only.
Deploy Morph on your own infra - on-prem or cloud.
Flexible, high-capacity rate limits.
99.9% uptime SLA with top-tier support .
Ready-to-sign agreements for enterprise compliance.
Defenders get refused. Attackers don't.
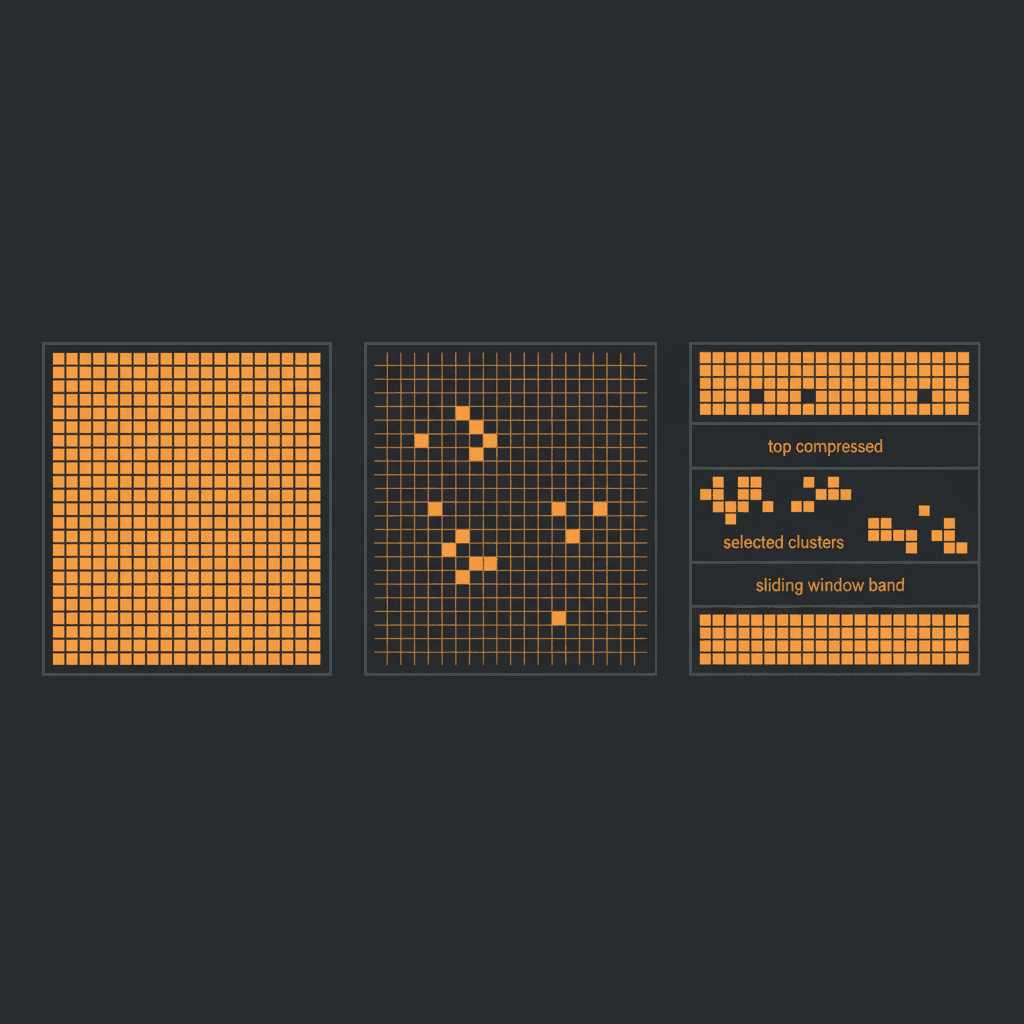
DeepSeek V4.1 Flash is live on Morph as morph-dsv41flash: a 552B-backbone MoE (about 763B total with Engram memory and vision) with 8B active for input and 16B for output, image input, native tool calling, thinking on by default with an adjustable budget, and a 1M context. $0.12 per million input, $0.008 cached, $0.80 output.
There are two kinds of inference: someone is waiting, or nobody is watching. The alpha lives at the ends. The open stack serves the middle.
Z.ai's GLM-5.2 lands within a few points of Claude Opus 4.8 on agent benchmarks at a fraction of the cost. Open weights don't serve themselves — here's how we make it fast, and how to reach it on Morph and OpenRouter.
Claude Code cost climbs because the whole agent loop runs on one frontier model. Here is what you actually pay for, why spend caps do not help, and how per-call model routing keeps the bill flat while token usage keeps growing.
How we serve open source models to be the best in class at coding agent workloads.
Critical takes on the latest in codegen.

Scale AI's benchmark for coding agents: 1,865 tasks across 41 repos. Leaderboard, scores, and why WarpGrep v2 lifts every model to #1.

Real data on when Codex destroys Claude Code and when it doesn't. Token economics, failure modes, and which $20/month actually delivers.

Every serious Cursor alternative benchmarked: Claude Code, Windsurf, Cline, Copilot, Aider, Codex, and OpenCode.

Claude Opus 4.5 leads SWE-bench at 80.9%. Grok 4 hits 81%. Scores, API pricing, speed, and why the harness matters more than the model.

How coding agents actually work, what separates harnesses from models, and where the field is headed.

Set up Playwright MCP in Claude Code, Cursor, or Codex. MCP vs CLI token costs and Stagehand comparison.

Native install, Homebrew, npm. Auth, CLAUDE.md, MCP setup, and troubleshooting.

Why LLMs degrade as context grows. 30%+ performance drop from lost-in-the-middle, and how subagent isolation reduces context rot by 70%.
The difference between a prompt and an agent that works. How to structure context so coding agents stay coherent across long sessions.

Technical analysis of AI coding agent harness architectures. Go-based OpenCode (75+ providers) vs Rust-based Codex (GPT-5).

Every head-to-head comparison in one place. Cursor, Claude Code, Copilot, Windsurf, Codex, Aider, Cline, and more.

Search-replace blocks with git merge syntax: limitations, accuracy issues, and why semantic editing achieves 98% vs 70% success rates.

Compare Composio, Cloudflare, Portkey, Kong, IBM ContextForge, and Docker across integrations, authentication, governance, and deployment.

Browserbase MCP gives coding agents hosted browser sessions, MCP tools, and a cleaner path from local browser loops to production browser infrastructure.

Where Stagehand fits next to Browserbase MCP, Playwright MCP, and Browser Use. Framework primitives, reliability, and when to use it.

Browserless API supports REST endpoints for task-shaped browser jobs and CDP WebSockets for Playwright or Puppeteer. Setup, tradeoffs, and self-hosting.

Run Browserless in your own environment with Docker, queue browser workloads, and expose Playwright/Puppeteer-compatible endpoints with better operational controls.

Set up Claude Code with LiteLLM as a unified endpoint. Learn when LiteLLM helps, how the proxy works, and the practical tradeoffs.

Claude is the broader Anthropic assistant stack. GitHub Copilot is the broader GitHub coding stack. Pricing, product scope, and workflow fit compared.

Kiro pricing is simple on paper: plans, credits, and overage. This guide breaks down the actual credit math, trial rules, and tradeoffs.

An LLM router classifies prompt difficulty in ~430ms and routes to the right model tier. 40-70% API cost savings with under 2% quality loss on hard tasks.

Claude Sonnet 4.5 costs 3.75x more than Haiku 4.5. Pricing, speed, quality tradeoffs, and how automatic model routing cuts costs 40-60%.

What an LLM gateway does, how it differs from a proxy and a router, key capabilities, open source options, and where intelligent routing fits in.

OpenRouter and LiteLLM solve provider access. Neither solves model selection. Comparison of routing logic, cost optimization, latency, and how intelligent routing fills the gap.

A practical guide to reducing LLM API costs. Five levers: model routing (40-70% savings), context compaction (50-70% token reduction), prompt optimization, caching (90% on cache hits), and batching (50% discount).

An AI infrastructure company writing honestly about the AI bubble. Bain found 10-15% productivity gains, METR showed devs 19% slower with AI, CodeRabbit measured 1.7x more bugs. What the data says, and what survives the correction.

What AI coding actually costs: token waste, agent loops, context bloat, subscription stacking. Real pricing data for Claude, GPT-5, Gemini, and how to cut spend 40-70%.

Real AI hallucination examples across legal, medical, and coding domains. Measured hallucination rates from 0.7% to 29.9%, why token prediction makes hallucination inevitable, and architectural strategies that reduce it.

An honest Claude vs ChatGPT comparison from a team that routes production traffic to both. Pricing, benchmarks, strengths, weaknesses, and why model routing beats picking one.

AI washing is adding 'AI-powered' to a product that uses no AI, or wrapping a ChatGPT API call and calling it proprietary technology. Documented SEC and FTC enforcement actions, the API wrapper problem, and a checklist for evaluating whether a vendor's AI claims are real.

An AI infrastructure company's honest assessment. METR found AI made experienced devs 19% slower. Bain measured 10-15% gains. CodeRabbit found 1.7x more bugs. Junior dev postings dropped 60%. The job is changing, not disappearing.